



We ran 58 live requests through EveryInfra across 20 platforms and 30 capabilities. Five cases, real numbers, clear limits, and failed calls that cost $0.
The same product can get very different star ratings in different places. ChatGPT’s latest reviews average 4.38 on Google Play and 4.34 on the App Store. OpenAI’s latest Trustpilot reviews average 1.20. In US data engineer job posts, only 14.5% fill the salary field, but another 50% state a pay range in the text. We got these numbers on October 26, 2026, from 10:52 to 11:15 Singapore time (SGT).
We sent 58 requests with one EveryInfra API key. They covered 20 platforms and 30 data capabilities and returned 3,168 rows. Billing charged 43 of them, $0.071703 in total. The 5 failed or empty calls all show charged_usd 0.
Key points
• One key, one endpoint: the catalog had 91 platforms and 426 data capabilities that day. 399 were available. Content and social is the largest group, with 48 platforms and 274 capabilities.
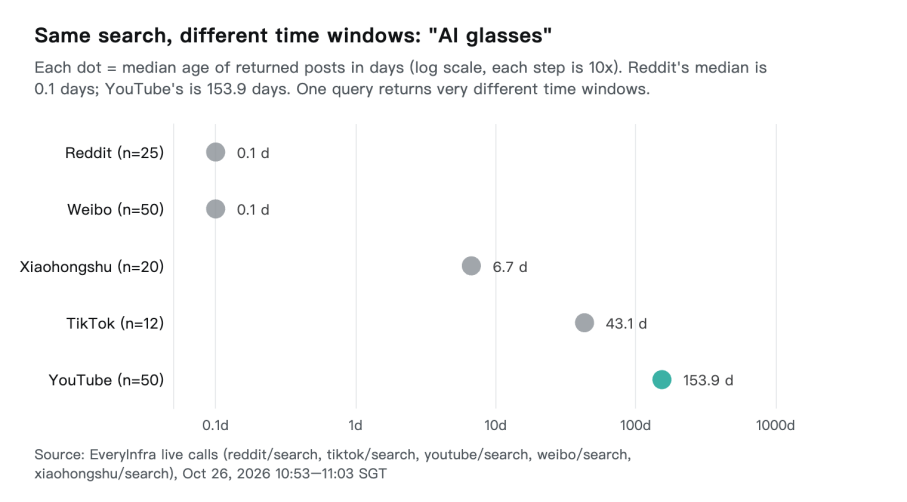
• Platforms differ a lot on the same task: Katz’s Delicatessen gets 26.8 new reviews a day on Google Maps and 0.28 on Yelp. For “AI glasses”, Reddit posts have a median age of 0.1 days and YouTube results 153.9 days.
• The field is not the whole story: of 110 US data engineer posts, 16 fill the salary field and 55 more state a range in the text. That is 64.5% in total.
• Failed calls cost nothing, with proof: 4 calls returned 503 and 1 returned no rows. All show charged_usd 0. The ledger shows a full refund of $0.00138889.
• Cost: 43 charged calls cost $0.071703. The lowest price for one call is $0.000556.
How we tested
We wrote five rules before we looked at any data. We did not change them later. First, each case uses at least two platforms, so we can compare one question across platforms. Second, a script, raw/analysis.py, computes every number from the raw responses.
Third, all exchange rates come from a central bank on a stated date. Fourth, we record failures, empty results and parameter errors as they happened. We did not retry until success and then hide the failures. Fifth, each result states its limits: sample size, date range and open questions.
Why these rules? A data platform proves itself with real responses, not with claims. The useful facts are what it returns, where it fails and how it bills. All requests used one test key and one endpoint, POST https://api.everyinfra.com/api/v1/social. Only the platform, action and params in the body changed.
EveryInfra allows 10 requests a minute per key. Our first batches were too fast, so 7 requests got a 429 response. Each 429 response says “Nothing was charged” and gives the wait time in seconds. We count these 7 requests in the totals below.
| Case | Capabilities | Singapore time | Rows returned | Charged (USD) |
| Retail prices: magnetic power banks | amazon/search, walmart/search, ebay/sold, temu/search, alibaba1688/search, amazon/profile | 10:52–11:04 | 423 | 0.009181 |
| Social topic: AI glasses | reddit/search, youtube/search, tiktok/search, youtube/comments, plus 4 Chinese platforms | 10:53–11:15 | 464 | 0.026366 |
| Local reviews: Katz’s and Lau Pa Sat | google_maps_reviews/search, google_maps_reviews/reviews, yelp/search, yelp/reviews, tripadvisor/search, tripadvisor/reviews | 10:55–11:01 | 287 | 0.011112 |
| Job market: data roles | linkedin/jobs (4 failed indeed/search calls) | 10:57–11:04 | 249 | 0.001112 |
| App reputation: ChatGPT and Temu | app_store/reviews, google_play/reviews, trustpilot/reviews | 11:00–11:08 | 1,600 | 0.008334 |
What EveryInfra is: one endpoint and a public catalog
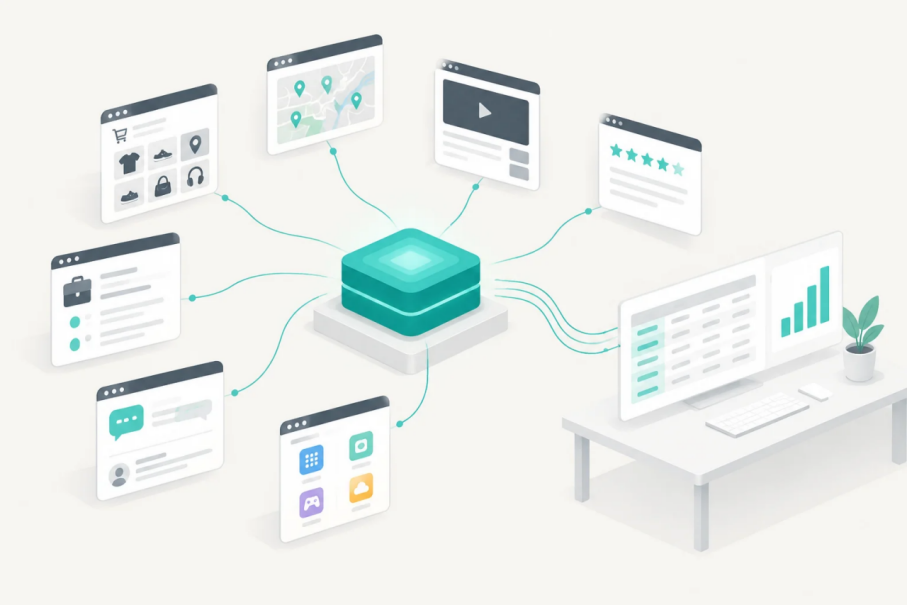
EveryInfra is a platform for public web data. You tell it the platform, the action and the parameters. Actions include search, details, comments, rankings and profiles. It returns JSON with named fields. All platforms share one endpoint and one API key.
You do not need a developer account on each platform. You also do not need to maintain page parsers, pagination or fixes after site redesigns.
The public catalog is the manual. Anyone can read GET /api/v1/social/catalog without a key. Each capability lists its required parameters, optional parameters, allowed values, returned fields, price and current status. We read the catalog at 10:49 SGT on October 26, 2026. It had 91 platforms and 426 capabilities.
399 were available and 27 were paused. Among the 399 available capabilities, the lowest price was $0.000556 per call and the median was $0.001389. 89.5% cost $0.001389 or less. You can use the catalog to choose before you build. You know the fields and the price before you write any code.
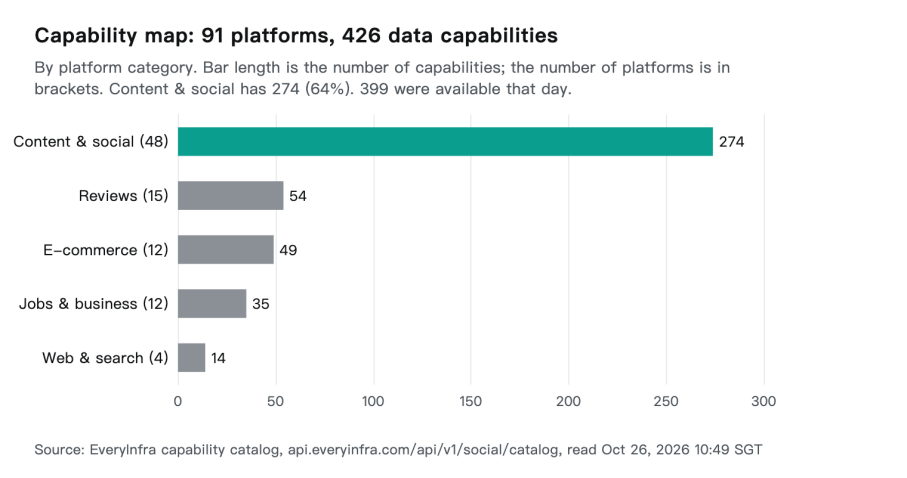
| Category | Platforms | Capabilities | Examples in the catalog | Typical use |
| Content and social | 48 | 274 | YouTube, TikTok, Reddit, Instagram, X, Xiaohongshu, Douyin | Topic tracking, creator research, comment analysis |
| Reviews | 15 | 54 | Google Maps reviews, Yelp, Tripadvisor, App Store, Google Play, Booking | Store reputation, app ratings, travel |
| E-commerce | 12 | 49 | Amazon, Walmart, eBay, Temu, Etsy, Shopee, 1688 | Product research, price checks, review mining |
| Jobs and business | 12 | 35 | LinkedIn, Indeed, Glassdoor, Seek, Trustpilot, Capterra | Hiring trends, salaries, company reputation |
| Web and search | 4 | 14 | General web, Yahoo Finance, Yandex, Similarweb | Web pages and market data |
The categories follow the rules of the EveryInfra market page. These rules group platforms by domain and tags. For this reason, Trustpilot and Capterra are in “Jobs and business”, not in “Reviews”. The table gives a general picture.
Content and social is the center of the catalog. E-commerce and reviews come next. If you need one platform, go to its page directly. Examples are the Amazon API, the YouTube API and the Google Maps Reviews API.
Case 1: Retail prices for one keyword on five platforms
The question: a seller wants to know how a product’s price changes from wholesale to retail, and at which step. We chose a crowded category with similar specifications: magnetic power banks. At 10:52 and 10:53 SGT, we called amazon/search (amazon.com), walmart/search, ebay/sold (sales in the last 30 days), temu/search and alibaba1688/search (the Chinese keyword for magnetic power bank). The five requests returned 422 rows and cost $0.007792.
We start with the medians. Amazon US: 23 products, median $29.99. eBay sold, new condition: 151 sales, median $25.11. Walmart: 20 products, median $23.67. Temu: 79 products, median $14.28.
1688 wholesale: 100 products, median CNY 52.0, which is $7.74. We used the central parity rate for October 23, 2026, from China’s State Administration of Foreign Exchange: USD 1 = CNY 6.7180. So the Amazon median is 1.19 times the eBay sold median for new units, 2.1 times Temu and 3.87 times the 1688 wholesale price.
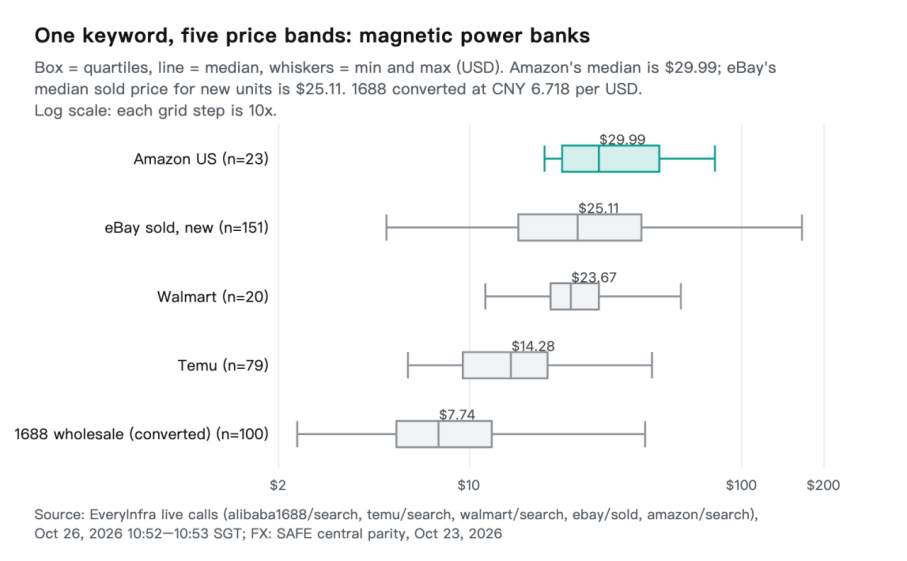
| Platform | Sample | Median (USD) | Quartile range (USD) | What to know |
| Amazon US | 23 | 29.99 | 21.99–49.99 | 9 are Anker. 5 ASINs are color variants of 2 models |
| eBay sold, new | 151 | 25.11 | 15.19–42.99 | Sold prices, not list prices. 191 of 200 sold from October 22 to 25 |
| Walmart | 20 | 23.67 | 19.94–29.99 | Mostly third-party sellers. Walmart.com sells 2 |
| Temu | 79 | 14.28 | 9.51–19.46 | Median discount from the strike-through price: 56.5% |
| 1688 | 100 | 7.74 (CNY 52.0) | 5.43–12.15 | Wholesale start price. 66 sellers are in Shenzhen |
Three details in the raw fields change how you use this table. First, Amazon returned three ASINs for the Anker 621: B099284SRR, B099W63VYV and B099Z2RJZW. All three show 21,149 ratings. Two ASINs for the Anker 633 both show 11,810 ratings.
These are color variants that share one review pool. If you count ASINs, Anker seems to hold 9 of 23 places. That number is too high. Remove duplicates by brand and rating count first, and then count.
Second, look at eBay. We asked for 30 days of sales. But ebay/sold returns at most 200 rows per call, and 191 of the 200 rows are from October 22, 2026, to October 25, 2026. So one call covered only the last four days. For the full 30 days, split the search by price band or by keyword, and send more calls.
The eBay numbers are still useful. They are prices that buyers paid, not prices that sellers asked for. The new-condition median of $25.11 is close to the Walmart median of $23.67. Both are below the Amazon median.
Third, Temu shows a strike-through price next to each price. The median gap is 56.5%. The median sold count is 450.5 units for the 72 items that show sales. The other 7 show 0 or no count, and the median of all 79 is 315. The strike-through price is a display field. It is not a past sale price.
So treat the “discount” as a display choice by the seller, not as a measured price cut. The 1688 side also gives a signal. 87 of the 100 products show past orders. 66 sellers are in Shenzhen, 6 in Dongguan, 6 in Guangzhou and 4 in Huizhou.
This matches the common view that consumer electronics supply is in the Pearl River Delta. But our sample is one keyword and one page. It cannot estimate national production.
These price bands will also move. The EU handling fee of EUR 2 per item is expected to apply from November 1, 2026 (see “Industry news” below). Send the same set of requests each week to see how the bands change. Our article on comparable offers on Amazon shows one way to do this.
For a weekly check, keep only the numbers that change decisions. These are the median per platform, the number of distinct top brands on Amazon and the Temu discount median. Also watch the change around November 1. The capability pages are eBay sold listings, Amazon search and the Walmart API.
Result and limits: one set of requests gets five price bands in about a minute. The Amazon median is 1.19 times the eBay sold median for new units and 3.87 times the 1688 wholesale price. These ratios apply only to this keyword and this sample. The 1688 price is a wholesale start price without shipping, certification or fees. Amazon returned one page of 23 items, in the platform’s own order. eBay covers only the last four days. Use this to answer “what is the price range, and who sells”, not to calculate profit.
Case 2: Social media topics return different time windows
The question: a brand or marketing team wants to know where people discuss “AI glasses”, which brands they mention and what users care about. At 10:55 and 11:03 SGT we called youtube/search (the query “AI glasses review”), tiktok/search and reddit/search (the query “AI glasses”). At 10:53–10:57 SGT, we also searched four Chinese platforms for the same topic: Xiaohongshu, Douyin, Bilibili and Weibo. At 11:07 SGT we used MCP to read 30 comments under a recent Ray-Ban Meta review on YouTube.
The first result is not about content, but it affects every comparison. One query returns very different time windows on different platforms. Reddit’s 25 results have a median age of 0.1 days, and all 25 are less than 7 days old. Weibo’s 50 results also have a median age of 0.1 days. Xiaohongshu’s 20 results have a median of 6.7 days.
TikTok’s 12 results have a median of 43.1 days. YouTube’s 50 results have a median of 153.9 days, and only 2 are less than 7 days old. So Reddit shows today’s conversation, and YouTube shows the most-watched reviews of the last half year. If you add up posts across platforms, you compare different time periods.
The second result is about brands. We matched brand names in titles and text. On YouTube, 45 of 50 results mention Meta or Ray-Ban. 16 mention Rokid, 8 mention Oakley, and 6 each mention XREAL, Even Realities and Google or Android XR.
On Reddit, 3 of 25 posts mention Meta or Ray-Ban and 2 mention Google or Android XR. On Bilibili, a Chinese video platform, 22 of 50 results mention RayNeo and 9 mention Xiaomi. These counts are not market share. They only show who appears in search results.
But they show one useful fact. A Chinese brand, Rokid, appears in 16 of the top 50 YouTube results. A team that only watches US platforms can miss the Chinese brands, and the reverse is also true.
| Platform | Results | Median age (days) | Median likes | Most mentioned brands (posts) |
| 25 | 0.1 | 1 | Meta/Ray-Ban 3, Google/Android XR 2 | |
| 50 | 0.1 | 0 | iFLYTEK 3, Quark 3 | |
| Xiaohongshu | 20 | 6.7 | 5 | Rokid 2 |
| TikTok | 12 | 43.1 | 2,098 | RayNeo 2, Even Realities 2 |
| YouTube | 50 | 153.9 | 1,391 | Meta/Ray-Ban 45, Rokid 16 |
The third result comes from comments. In the 30 YouTube comments, 7 compare the second and third generation of Ray-Ban Meta. 3 mention a display or HUD. 2 mention price and 1 mentions battery. The US conversation has moved to “is the upgrade worth it”.
In 171 comments on Chinese platforms, the top theme is live translation, with 14 comments. Next are prescription lenses (6) and battery life (6). Only 2 ask about price. For product and content teams, this is more useful than like counts. Users ask about lenses and translation, not about camera pixels.
| Comment theme | YouTube, 30 comments | Chinese platforms, 171 comments |
| Upgrade (second vs. third generation) | 7 | — |
| Display or HUD | 3 | — |
| Live translation | — | 14 |
| Prescription lenses | 0 | 6 |
| Battery and charging | 1 | 6 |
| Price | 2 | 2 |
Compare the conversation with events. On October 20, 2026, EssilorLuxottica said in its third-quarter report that new AI glasses will launch for the holiday season (see “Industry news” below).
Our Reddit results at 11:03 SGT have a median age of 0.1 days. This makes Reddit a good place to see how people react after such news. Reddit is also closing its public API, so this source needs a plan. See the “Industry news” section below.
Result and limits: for cross-platform topic tracking, align the time windows first. Then compare counts and engagement. A few requests give a first picture of brand mentions and user questions. The samples are small: TikTok returned 12 posts and Reddit 25.
All are the top results in the platform’s own order, not the full conversation. Brand matching uses keywords, so it misses posts that use nicknames or model numbers. We read comments under one YouTube video and four Chinese posts only. For more, see the YouTube search API, the Reddit API and the TikTok API.
Case 3: Local reviews arrive at very different speeds
The question: people in restaurants and travel often ask which platform to read for a place’s reputation. We chose two busy places. Katz’s Delicatessen in New York is one. Lau Pa Sat in Singapore is the other.
It is a Victorian food market, and Singapore made it a national monument in 1973 (Roots, National Heritage Board). From 10:57 to 11:00 SGT, we found Katz’s with yelp/search and google_maps_reviews/search. Then we read reviews with yelp/reviews and google_maps_reviews/reviews (the newest 100). From 10:55 to 10:57 SGT, we did the same for Lau Pa Sat with Google Maps and Tripadvisor.
The largest difference is speed. Katz’s newest 100 reviews on Google Maps span 3.7 days, which is 26.8 reviews a day. Its newest 10 reviews on Yelp span 35.9 days, which is 0.28 a day. That is a 95.7 times gap.
Lau Pa Sat shows the same pattern. Its newest 100 Google Maps reviews span 12.1 days, which is 8.27 a day. Its newest 50 Tripadvisor reviews span 297 days, which is 0.17 a day. That is a 48.6 times gap.
To know what went wrong last week, Google Maps gives you tens of times more reviews. To read long reviews with trip context, Tripadvisor is more complete. All 50 Tripadvisor reviews have text and a trip type: 20 families, 19 couples and 8 groups of friends.
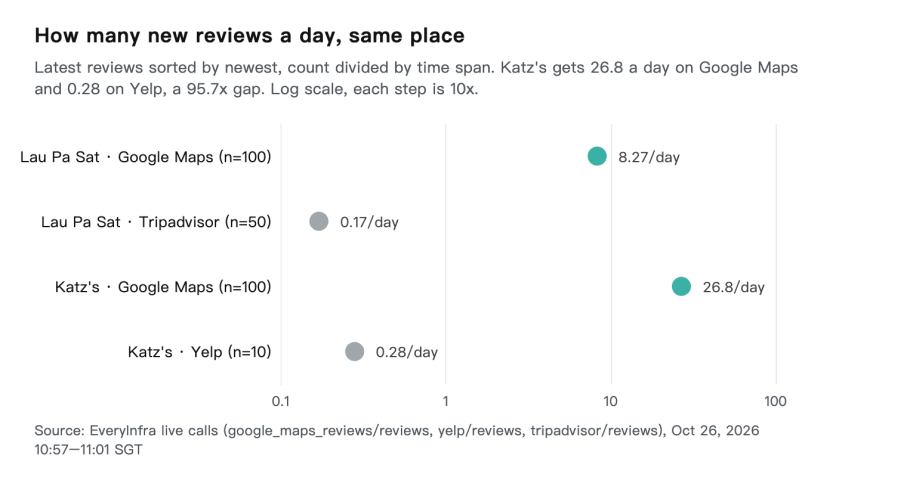
| Measure | Katz’s, Google Maps | Katz’s, Yelp | Lau Pa Sat, Google Maps | Lau Pa Sat, Tripadvisor |
| Page rating / total reviews | 4.5 / 56,283 | 4.1 / 17,124 | 4.4 / 39,338 | 4.2 / 2,567 |
| Reviews we read | 100 | 10 | 100 | 50 |
| Time span (days) | 3.7 | 35.9 | 12.1 | 297.0 |
| New reviews per day | 26.8 | 0.28 | 8.27 | 0.17 |
| Mean stars, latest batch | 4.45 | 4.20 | 4.61 | 4.40 |
| Reviews with text | 56 | 10 | 34 | 50 |
The second difference is the amount of text. Of Katz’s newest 100 Google Maps reviews, 56 have text. The other 44 are stars only. 7 of the 100 are one-star reviews.
At Lau Pa Sat, only 34 of 100 have text, and 74 come from Local Guide accounts. Stars give an average, but they do not explain the reasons. This is why the official APIs are not enough here. Google’s Places API documentation says a place returns up to five reviews (see the screenshot below).
Yelp’s reviews endpoint returns up to three review excerpts. Five or three reviews work in an app screen. They do not support weekly counts or a search for the causes of bad reviews.
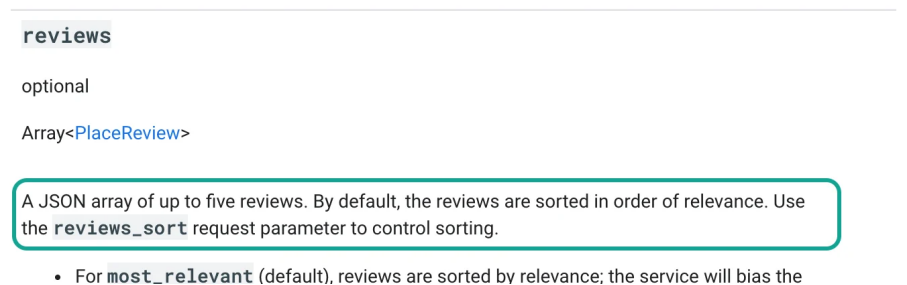
Source: Google Maps Platform documentation (screenshot of the original page)
Also separate the page rating from the latest batch. The page rating averages all past reviews. Katz’s Google Maps page shows 4.5, and the newest 100 average 4.45. On Yelp, the page shows 4.1 and the newest 10 average 4.20. For an owner, “the last two weeks are 0.2 above the long-term average” says more than “4.4 overall”.
The first step is to match the same place across platforms. On Google Maps, the place_id is the most stable key. See our article on Google Maps place_id deduplication. The capability pages are Google Maps reviews and Yelp reviews.
Result and limits: for recent news about a place, Google Maps gives 48 to 96 times more reviews than Tripadvisor or Yelp. For long reviews and trip context, Tripadvisor is more complete. These ratios come from two places and one batch each. Popular tourist places and small local shops will differ.
The Yelp endpoint returns at most 10 reviews per call, so use pages for more. Remove personal data such as names and avatars before analysis. All statistics in this article use only stars, dates and text themes.
Case 4: The job market keeps salaries in the text
The question: recruiters, workforce analysts and labor researchers want to know the skills and pay for a role in different cities. At 11:00 SGT we called linkedin/jobs for “data engineer” in the United States and got 110 posts. At 10:59 SGT we called it for “data analyst” in Singapore and got 139 posts. The two calls cost $0.001112 together.
We also tried indeed/search twice for each country at about the same time. All four calls returned 503, and none was charged. See the billing section below.
The most valuable result is about pay. Of the 110 US posts, only 16 (14.5%) fill the structured salary field. We searched the job description text for a “number to number” pay range with a regular expression. We found 55 more posts.
So 71 posts state pay, which is 64.5%. If you read only the field, you miss three quarters of the pay data. In Singapore, 2 posts fill the field and 3 more state a range in the text. That is 5 posts, or 3.6%.
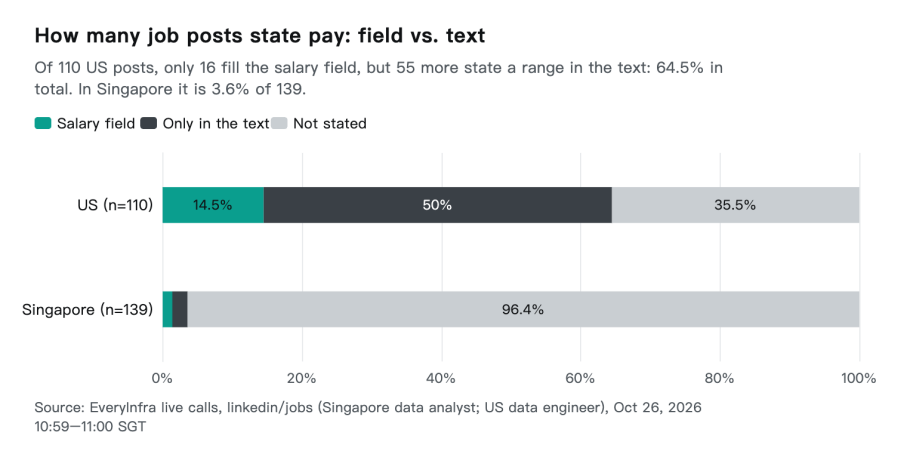
Why is the gap so large? Several US states require a pay range in job ads. New York Labor Law Section 194-B requires employers with four or more employees to list a pay range (New York State Department of Labor). In Washington, employers with 15 or more employees must show a salary range and a benefits description in each posting (Washington L&I). Colorado’s Equal Pay for Equal Work Act requires pay disclosure in all internal and public job postings (Colorado CDLE).
Singapore has no general rule of this type. But for Employment Pass roles, the Ministry of Manpower requires an ad on the government job site MyCareersFuture with a salary range. The maximum cannot be more than two times the minimum (Ministry of Manpower). So in Singapore, LinkedIn is not the place to find pay data.
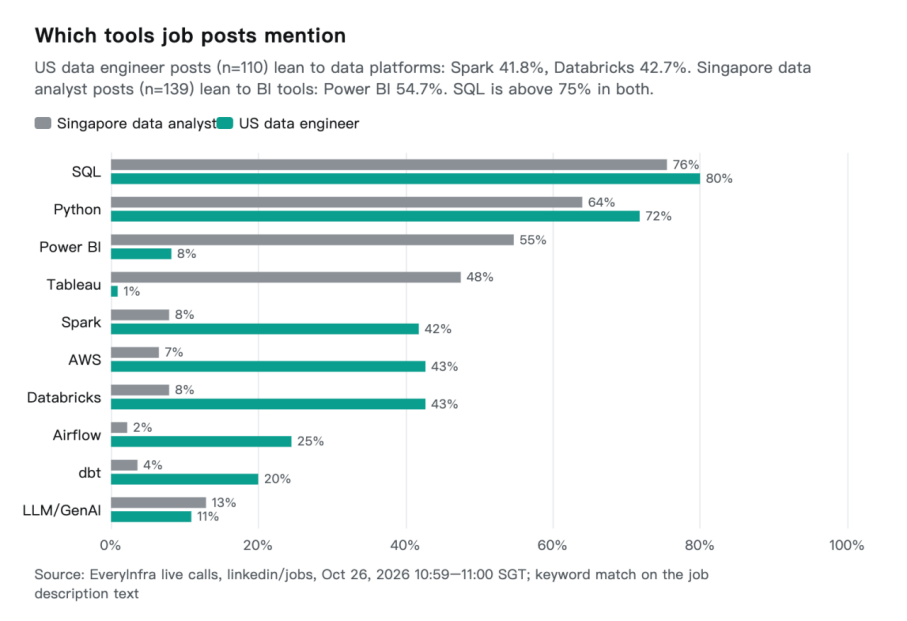
The skills match common sense, but the numbers give scale. In US data engineer posts, SQL appears in 80.0% and Python in 71.8%. AWS and Databricks appear in 42.7% each, Spark in 41.8%, Airflow in 24.5% and dbt in 20.0%. This is a data platform profile.
In Singapore data analyst posts, SQL appears in 75.5%, Python in 64.0%, Power BI in 54.7% and Tableau in 47.5%. This is a reporting profile. Large language models or generative AI appear in only about one in ten posts: 10.9% in the US and 12.9% in Singapore. In these two samples from October 2026, AI skills are a bonus, not a core requirement.
The data has two more traps. First, the applicant count is in bands. 44 US posts show exactly 200, which is the “over 200 applicants” label. 24 show 25, which is the “be among the first 25” label. So a median of 137.5 applicants is only a lower bound.
Second, the 110 US posts have only 93 distinct title and company pairs. Deloitte alone has 10 posts. One role appears in many cities, so a simple count overstates hiring at large firms. Our article on job posting data as buying signals shows what you can build with this data. The capability page is LinkedIn jobs.
Result and limits: in job data, pay is the field that analysts miss most often. It is more often in the text than in the field, so extract it from the text first. Our regular expression finds only “number to number” ranges. It misses “up to $200K” and hourly rates, so 64.5% is a lower bound.
LinkedIn decides the order and coverage of search results, so one call is not a full census. The official route does not help here. LinkedIn’s Job Posting API says it does not accept new partners now. Also, that API is for posting jobs, not for reading other companies’ jobs.
Case 5: One product, three places, three scores
The question: growth teams, brand teams and investors often use app store ratings as a reputation signal. We wanted to know how much the score changes in another place. At 11:00–11:01 SGT, we used app_store/reviews to read the newest 500 US App Store reviews of ChatGPT and of Temu. We used google_play/reviews to read the newest 200 Google Play reviews of each. At 11:07–11:08 SGT, a Python script called trustpilot/reviews for openai.com and temu.com and read the newest 100 reviews of each. The six requests returned 1,600 reviews and cost $0.008334.
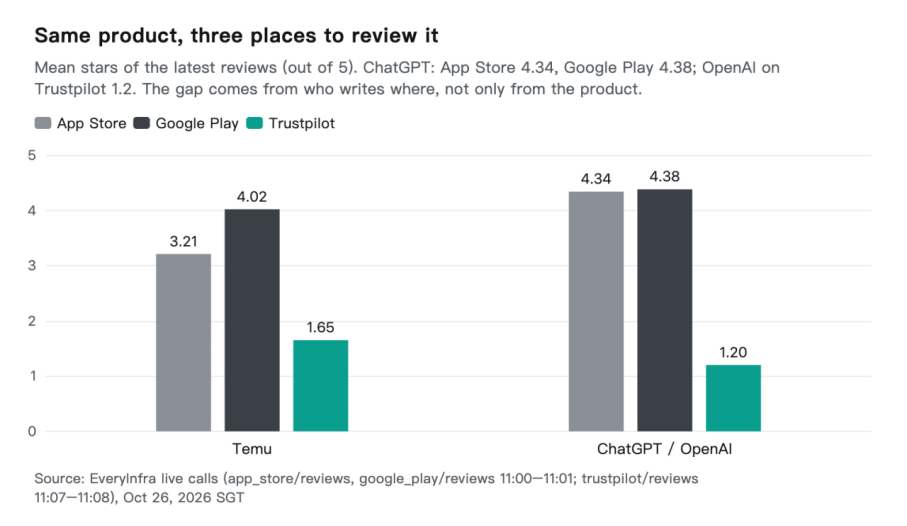
| Product | Platform | Sample | Mean stars | One-star share | Five-star share | Time span |
| ChatGPT | App Store | 500 | 4.34 | 11.6% | 78.0% | Oct 22–24 |
| ChatGPT | Google Play | 200 | 4.38 | 8.0% | 73.5% | Oct 25 |
| OpenAI | Trustpilot | 100 | 1.20 | 89.0% | 2.0% | Aug 18 – Oct 25 |
| Temu | App Store | 500 | 3.21 | 33.4% | 42.4% | Oct 13–24 |
| Temu | Google Play | 200 | 4.02 | 17.0% | 63.0% | Oct 24–25 |
| Temu | Trustpilot | 100 | 1.65 | 77.0% | 10.0% | Oct 21–26 |
Trustpilot shows the largest gap. OpenAI’s newest 100 Trustpilot reviews average 1.20, and 89% are one star. ChatGPT’s newest Google Play reviews average 4.38 at the same time. The reason is not the product. The reason is who writes where.
Trustpilot returns a source field for each review. For Temu, 99 of 100 reviews are “Organic”. This means the users came to write on their own, and the company did not invite them. Users who come on their own often have a problem, such as shipping, refunds or support. App stores often ask users for a rating inside the app, so satisfied users also rate.
The two systems measure different things. App store scores are closer to “everyday satisfaction”. Trustpilot scores are closer to “how unhappy people with problems are”. Trustpilot’s Trust Centre says that companies can invite customers to review, and that consumers can also write at any time. Do not use one score in place of the other.
Speed also differs a lot. ChatGPT’s newest 200 Google Play reviews cover about 1.2 hours. Temu’s newest 200 cover about 7 hours. OpenAI’s 100 Trustpilot reviews span 68.7 days.
Versions also show problems. On the App Store, Temu version 4.90.0 has 132 reviews with a mean of 2.92. The previous version, 4.89.0, has 236 reviews with a mean of 3.34. The next version, 4.92.0, has 69 reviews with a mean of 3.28.
A score by version helps a product team more than one score on a store page. See our article on review data products. The capability pages are App Store reviews, Google Play reviews and Trustpilot reviews.
Result and limits: the latest scores for one product can differ by more than 3 stars across three review platforms. ChatGPT gets 4.38 on Google Play and OpenAI gets 1.20 on Trustpilot. The difference comes mostly from how each platform collects reviews. One platform’s score cannot stand for reputation. The samples are the newest batch on each platform, and they span from about one hour to more than two months.
Holidays, releases and promotions can move scores for a short time. Temu’s Trustpilot reviewers are mostly in the UK (34) and the US (33), so the result does not describe other markets. The official APIs also serve only your own apps. Apple’s App Store Connect API reads reviews for your own app. The Google Play Developer API reviews.list returns only your own app’s reviews from the last week.
Compared with other ways: your own scraper, official APIs, general web scraping
There are three common ways to get public data. You can write your own scraper. You can use the platform’s official API. Or you can use a general web scraping tool that fetches the full page, and then parse it yourself.
The table below contains only facts that you can check. It does not rank the options. Each one makes sense for some needs.
| Item | Your own scraper | Official platform APIs | General web scraping | EveryInfra (tested here) |
| Whose data | Any public page | Mostly your own account or app. App Store Connect reads only your own app’s reviews. Google Play gives only your own app’s reviews from the last week. Amazon SP-API needs seller authorization | Any public page | Public data from the 91 platforms in the catalog |
| Data per call | Your choice | Google Places returns up to 5 reviews per place. Yelp returns up to 3 excerpts | One page | Up to 500 rows in one call in this test (app_store/reviews) |
| Access | Open | TikTok Research API is for non-profit researchers in the US and Europe. LinkedIn’s job API accepts no new partners now. eBay sales history is a limited release | Sign up | Sign up, one key |
| Quota and price | You pay for servers, proxies and people | YouTube gives 10,000 units a day by default. X charges per use and caps reads at 3 million posts a month | Per request or per page | From $0.000556 per call. Failed and empty calls are not charged |
| What you get | HTML that you parse | Structured fields | HTML, a rendered page or text | JSON with named fields that the catalog lists |
| Site redesigns | You fix them | The platform maintains the API, but can retire it or narrow it | You fix the parser | EveryInfra maintains it |
The table uses these sources. Access rules for app reviews are in the App Store Connect API and the Google Play Developer API docs. Seller access is in Amazon SP-API getItemOffers. Review limits are in the Google Places API and the Yelp reviews endpoint. Research access is in TikTok Research Tools.
Partner access is in the LinkedIn Job Posting API and the eBay Buy API requirements. Quotas and prices are in the YouTube quota calculator and X API pricing. Common open-source tools for your own scraper are Scrapy (source code) and Playwright. With any method, follow the robots.txt rules in RFC 9309 and the site’s terms.
How to choose: if you need only your own account, app or store, start with the official API. It gives back-office data that nobody else can get, such as orders, ads and messages. If the site is not in any catalog, or you need the full page layout and images, write your own scraper or use general scraping. Do you need public data about others on many platforms, with fixed fields, clear errors and pay per call?
Then a unified data API saves the most work. You can also combine them. Use official APIs for your own back office and EveryInfra for market data. Use your own scraper for sites outside the catalog.
Three ways to connect: curl, Python and MCP
curl: see data with one command
All platforms use the same endpoint. Only platform, action and params change. Here is the Amazon request from Case 1, exactly as we sent it. The key is in an environment variable.
curl -X POST https://api.everyinfra.com/api/v1/social \
-H “Authorization: Bearer $EVERYINFRA_API_KEY” \
-H “Content-Type: application/json” \
-d ‘{“platform”:”amazon”,”action”:”search”,”params”:{“keyword”:”magnetic power bank”,”domain”:”amazon.com”,”limit”:50}}’
On October 26, 2026, at 10:52 SGT, this request took 56.5 seconds and returned 23 products. Its billing.charged_usd was 0.002236. For Walmart, change only “platform”:”walmart” and remove the domain. The response has the same shape. The results list holds the rows, and billing shows the charge for this call.
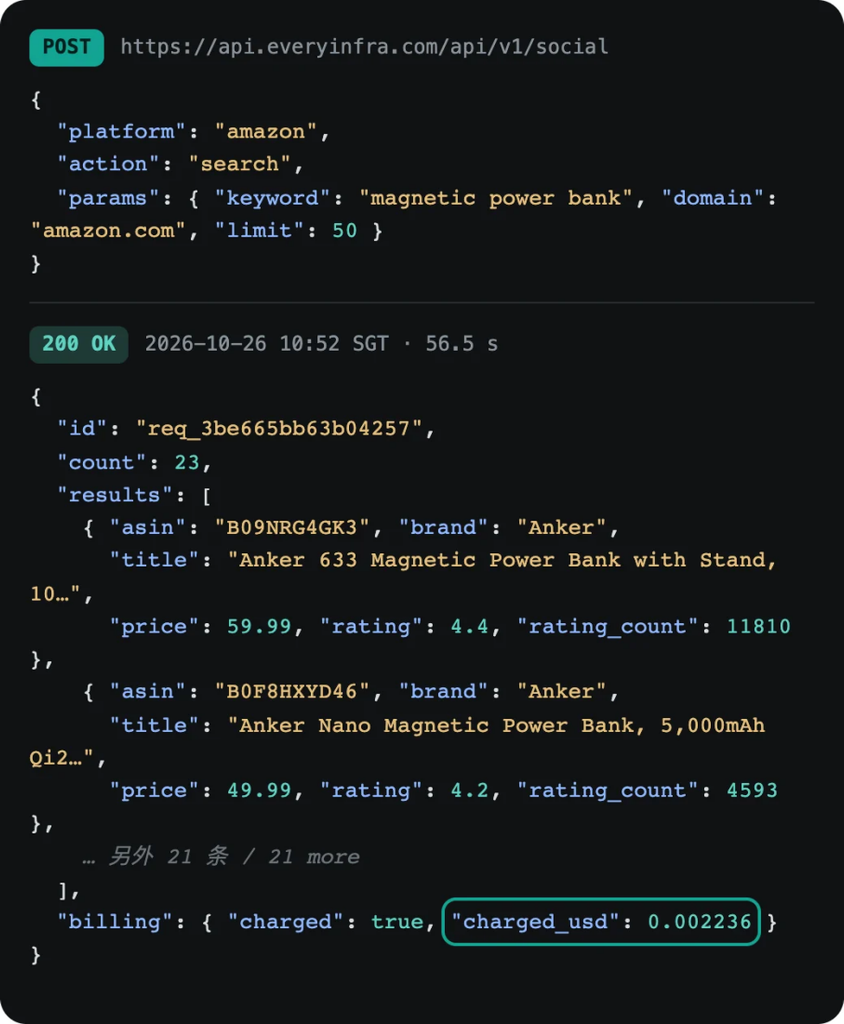
The response fields match response_fields in the catalog. For amazon/search, the catalog lists 20 fields. Here are the ones we used most, with the values of the first row.
| Field | Meaning | First row in this test |
| asin | Amazon product ID. Color variants of one model can have different ASINs | B09NRG4GK3 |
| title | Product title | Anker 633 Magnetic Power Bank with Stand… |
| brand | Brand | Anker |
| price / list_price | Current price / strike-through price, can be empty | 59.99 / empty |
| rating / rating_count | Star rating / number of ratings, shared by variants | 4.4 / 11,810 |
| in_stock | Item is available | true |
| seller_name | Seller | AnkerDirect |
| bestseller_ranks | Category ranks (full values from amazon/profile) | See below |
For deeper fields, use a detail capability. At 11:04 SGT, we called amazon/profile for the Anker 621. It returned bestseller_ranks: number 133 in Cell Phones & Accessories, and number 4 in Cell Phone Portable Power Banks.
Python: only requests
The EveryInfra docs use Python examples that need only the requests library (docs). You can also generate a client in any language from the OpenAPI 3.0 specification. Here is the script from Case 5 that reads Trustpilot reviews. It runs as shown.
session = requests.Session()
session.headers.update({"Authorization": f"Bearer {os.environ['EVERYINFRA_API_KEY']}"})

for company in ["temu.com", "openai.com"]:
    body = session.post("https://api.everyinfra.com/api/v1/social", json={
        "platform": "trustpilot",
        "action": "reviews",
        "params": {"company": company, "sort": "recency", "limit": 100},
    }, timeout=300).json()
    stars = [r["rating"] for r in body.get("results", []) if r.get("rating") is not None]
    print(company, len(stars), round(sum(stars) / len(stars), 2), body["billing"]["charged_usd"])
We ran it at 11:07 and 11:08 SGT. The output was: temu.com, 100 reviews, mean 1.65, charged 0.001389. openai.com, 100 reviews, mean 1.2, charged 0.001389. Note that sort must be recency here, not newest as on other platforms. A wrong value returns 422 with the allowed values (see the Reddit example in the billing section).
Set the client timeout to 300 seconds. The server gives a synchronous call about 85 seconds of work time, but the client also waits for the network and the queue. The slowest call in this test took 92.0 seconds, so do not set the timeout below 100 seconds. For slow tasks, add “mode”: “async” to the body and poll the job. Polling is free.
MCP: use it inside an AI client
EveryInfra runs a remote MCP server at https://api.everyinfra.com/mcp with 25 tools. Add the configuration below to a client that supports remote MCP, such as Claude, Cursor or ChatGPT. Then you can call the same capabilities in plain language.
{
  "mcpServers": {
    "everyinfra": {
      "url": "https://api.everyinfra.com/mcp",
      "headers": { "Authorization": "Bearer <your EveryInfra API key>" }
    }
  }
}
At 11:06 SGT we used the MCP tool everyinfra_call_api to read the Weibo trending list. It returned 46 topics and cost $0.000556, the same price as a direct call. At 11:07 SGT we used the same tool to read 30 comments under a YouTube review. The MCP result is the API JSON, in result.content[0].text. We asked for protocol version 2026-07-28 in the handshake.
The server agreed on the 2025-11-25 version. The 2026-07-28 version removes protocol sessions (key changes). Current clients accept the older version. For client setup, see remote MCP setup and the MCP server page.
For your first call, sign up and create a key in the console, as the quick start shows. Send one request with one target and a small limit. Check the fields and the price. Then scale up.
Billing and free failures: the ledger of 58 requests
EveryInfra charges per call, with no monthly fee. The catalog shows the price of each capability. Each response shows the charge for that call in billing.charged_usd. We wrote all 58 requests into a ledger, raw/calls.log. 43 succeeded and were charged, $0.071703 in total.
5 failed or returned no rows, and all show charged_usd 0. 9 were rejected before any work started: 7 got 429 (rate limit), 1 got 422 (bad parameter) and 1 got 401 (no key). None of the 9 reached billing. The last one was a free ledger lookup.
Figure 13. Billing outcome of the 58 requests (1 free ledger lookup not shown)
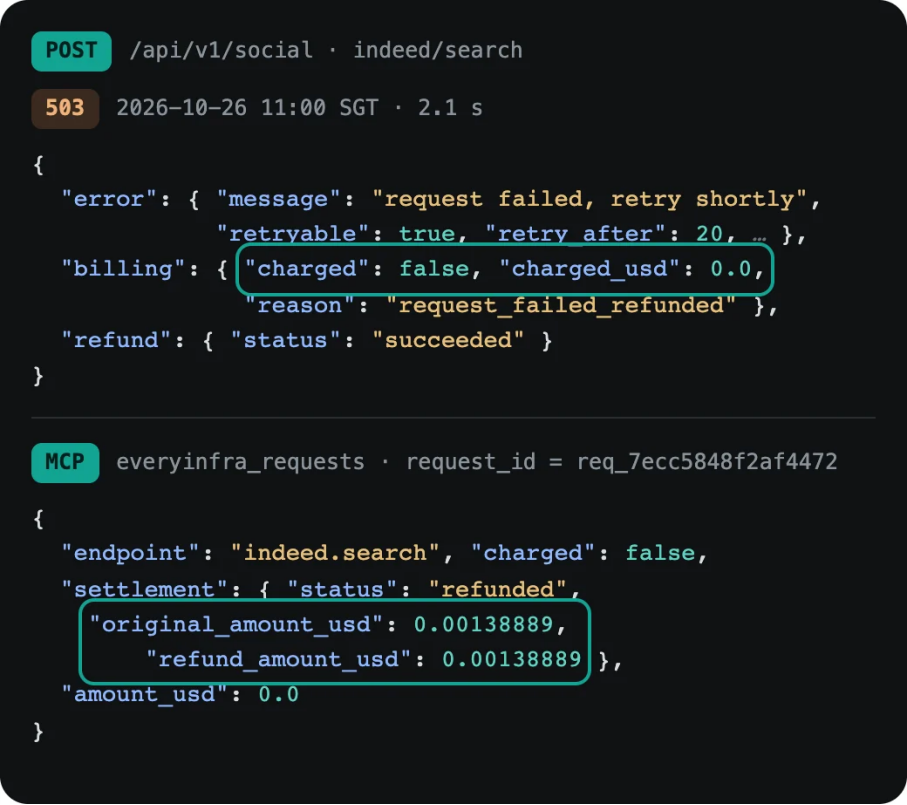
The failed calls show the most. At 11:00 SGT we called indeed/search and got 503. In the response, billing.charged is false, charged_usd is 0 and reason is request_failed_refunded. refund.status is succeeded, and the response says to retry after 20 seconds.
Then we used the MCP tool everyinfra_requests to look up this request by its request_id. The settlement record shows an original amount of $0.00138889, a refund of $0.00138889 and a final amount of 0. So the system holds the price first. When the call fails, it refunds the same record in full, and the ledger shows each step.
Figure 14. One 503 failure: no charge in the response, and a full refund in the ledger. Source: EveryInfra API response screenshot https://everyinfra.com/en/build/failure-refund-reconciliation
Empty results work the same way. At 11:06 SGT we called ebay/sold on purpose with a minimum price of $999,999 for the last 7 days. It returned 0 rows with reason empty_result_refunded and charged_usd 0. Bad parameters stop before any work starts.
At 10:55 SGT we sent sort: “new” to reddit/search. It returned 422. The error message lists the allowed values and a suggestion:
{“error”: {“code”: “invalid_value”,
“message”: “`sort` must be one of: controversial, newest, popular, relevance, rising, top (got ‘new’)”,
“param”: “sort”, “did_you_mean”: [“newest”],
“next_steps”: [“Change only `sort` to a value in `allowed`, then resend. Nothing was charged.”]}}
People and AI clients can both read this message. An AI client can read did_you_mean, change the value to newest and send again. We did this at 11:03 SGT. The call returned 25 posts and cost $0.000556.
One more billing detail is useful. Some capabilities, such as Douyin comments, show rows_per_unit: 20 in the catalog. They bill per block of 20 rows (Douyin catalog entry). At 11:15 SGT we asked for 150 comments, so the system held 8 blocks. It returned 75 comments, so it charged only 4 blocks, $0.002222, and refunded the other 4 at once.
Only 4 capabilities in the catalog bill this way. All others charge one price per call, whatever the limit. So it is best to set the limit to the maximum that the capability allows. Our app_store/reviews call returned 500 reviews for $0.001389. See the pricing page for price tiers and failure refund reconciliation for how to check refunds.
For speed, the 40 successful synchronous calls took from 2.4 to 92.0 seconds, with a median of 20.9 seconds. 28 returned within 30 seconds and 4 took more than 60 seconds: two LinkedIn calls, one Yelp search and one Google Maps search. All failed calls returned in 0.1 to 2.4 seconds. For real-time apps, use async mode for slow capabilities. For a daily report, this speed is enough.
For IPFoxy readers: use proxies for your stores, not for public data
This section is for readers of IPFoxy. Many cross-border sellers run stores on several Amazon marketplaces, such as the US, Germany and Japan. They give each store a dedicated residential proxy in the store’s country. They use that IP to log in to Seller Central, change prices and answer buyers.
This keeps the environments of different stores apart. The IPFoxy website says its network covers more than 200 countries and regions with a pool of 90 million IPs. It offers rotating residential, dedicated residential, data center and mobile proxies. Its rotating residential proxies start at $1.99/GB, and dedicated residential proxies start at $7.99 a month.
The IPFoxy website lists “e-commerce store management” and “market data research” as typical uses. Both seem to need proxies, but they need different exits. Store management needs a stable, fixed IP for each store. Market research needs wide coverage, large volume and short sessions. When sellers run both tasks in the same environment, costs go up and the store environments get messy.
Sellers also need a lot of public data every day. What does a competitor charge on each marketplace? Is the item in stock? How many ratings does it have? If you open these pages through your store proxies, three problems appear.
You use fixed IPs that your stores need. Your store environments collect browsing history of competitor pages. And you check one marketplace and one page at a time. You do not need your store’s identity to read public data. We tested this.
At 11:03 SGT, from Singapore, we sent three amazon/search calls at the same time. The queries were “Anker MagGo Power Bank” on amazon.com, “Anker MagGo Powerbank” on amazon.de and a Japanese query on amazon.co.jp. The three calls cost $0.006708 and took 54 to 57 seconds.
| ASIN | US price | Germany price | Germany price in USD | In stock in Germany | Ratings US / Germany |
| B0CFDPQXN4 | $79.99 | €56.98 | $63.78 | Yes | 9,058 / 9,036 |
| B0D7HZ4G5G | $79.99 | €47.92 | $53.64 | Yes | 10,137 / 10,109 |
| B09NRG4GK3 | $59.99 | €49.99 | $55.95 | Yes | 11,810 / 10,364 |
| B0CXDXP8VR | $59.99 | €49.99 | $55.95 | Yes | 10,456 / 10,147 |
| B0DGKWTQQC | $49.99 | €49.99 | $55.95 | Yes | 3,679 / 3,512 |
| B099284SRR | $29.99 | No price | — | No | 21,149 / 17,748 |
All 43 US results have a price. Only 9 of the 20 German results have a price. The other 11 return in_stock: false and no price. In Japan, 18 of 42 results have a price.
The US and German results share 11 ASINs, and 5 of them have a price on both sites (the first five rows). At the ECB rate of October 23, 2026, the German prices are $53.64 to $63.78. The first four are 7% to 33% below the US price. The fifth, B0DGKWTQQC, is 12% above.
The two prices mean different things. German prices include 19% VAT, and US prices do not include sales tax. So this compares shelf prices, not margins.
Japan gives another warning. Its 42 results share no ASIN with the US or German results. The Anker MagGo 10,000mAh is B0CFDPQXN4 in the US and Germany. In Japan, the matching item is B0CFTWFH82 at ¥9,990. At the ECB rates of the same day, USD 1 = ¥156.80, so this is about $63.71.
Cross-market price checks cannot rely on ASINs alone. Match items by brand, model and capacity first, and then compare prices. The 11 shared ASINs between the US and Germany are a lucky case, not a rule. A seller on several marketplaces should keep this match table up to date each week.
The split of work is simple. For public data such as competitor prices, stock and ratings, use the data API. One set of calls covers three marketplaces. It does not use your store IPs and leaves no browsing history in your store environments. To log in as a store, or to check what a German buyer sees on the page, use an IPFoxy exit in that country.
For example, B099284SRR has no price on the German site in our data. Is it out of stock, or is the price hidden from our request? The API data cannot answer this. A browser with a German IP can answer it in one visit. Use a sticky session for this check. Then the product page, the address change and the price view all come from one German IP.
Then write the result in a note column of your data table. Examples are “out of stock”, “price shown only for some regions” or “price shown after a variant choice”. Next week, the same empty price needs no new check. The EveryInfra docs have a section on use with an IPFoxy proxy.
IPFoxy is the exit for your own requests. Data API calls go direct, without the proxy. The example sets trust_env = False, so data calls skip the system proxy and use no proxy traffic.
To split the work by marketplace, follow four steps. Each step uses numbers from the three-marketplace test above.
- Set a local query for each marketplace. We used “Anker MagGo Power Bank” on amazon.com, “Anker MagGo Powerbank” on amazon.de and a Japanese query on amazon.co.jp. We sent the three calls at the same time. They returned 43, 20 and 42 results. The German site returned less than half of the US count. One English query copied to another site can return far fewer items. So set the query for each site separately and keep it in your table.
- Make two lists: items with a price and items without a price. All 43 US results have a price. In Germany, 9 of 20 have a price, and 11 return in_stock: false with no price. In Japan, 18 of 42 have a price. Items with a price go into the price table. Items without a price go into a check list. This step reads only public data. It needs no store identity and no store exit.
- Match the items first, then compare prices. The US and German sites share 11 ASINs, and 5 have a price on both sites. These go straight into the table above. Japan shares no ASIN with the other two sites. Match those items by brand, model and capacity, for example B0CFDPQXN4 in the US and Germany and B0CFTWFH82 in Japan. Update this match table each week, and add a row for each new item.
- Send only the check list to an exit in that country. In this test, the 11 German items without a price are the only part of the data that needs a look as a German buyer. Open them with a German dedicated residential proxy, or with a sticky session of a rotating residential proxy. Find out if the item is out of stock, shows a price only in some regions or needs a variant choice first. Write the result in the note column. Do the same for Japan.
The data API cannot replace store logins at all. Orders, ads, performance and buyer messages need your store identity. A dedicated IP per store, from $7.99 a month, is the base for that work.
A seller of power banks on the US, German and Japanese sites can give these tasks to the data API. Each morning, run amazon/search once per marketplace for your keywords, and check the price and stock of the top 50 results, for about $0.0067. Each week, call amazon/profile for your own item and three main competitors, and record the category rank. In this test, the Anker 621 ranks 4th in Cell Phone Portable Power Banks. Each call costs $0.001389.
After a launch, read the newest reviews each week with amazon/reviews to find the main complaints. At this rate, the API costs less than $1 a month. None of these calls go through your store proxies. Use the IPFoxy exit of a country only for two tasks. One is to see a page as a buyer there.
The other is to check local shipping and promotions.
| Task | Tool | Cost or scope in this test |
| Competitor price and stock on 3 marketplaces | amazon/search, no proxy | $0.006708 for 105 items |
| Category rank of one item | amazon/profile, no proxy | $0.001389 per call |
| Check of items without a price | Proxy exit in that country | Only the items on the check list |
| Store login, orders, ads, messages | Dedicated residential IP per store | From $7.99 a month per IP (IPFoxy website) |
This split also makes faults easier to find. For a data problem, check the API response first. For a login problem, check the proxy and account environment first. Also see why web scraping needs proxy IPs.
Which IPFoxy product fits which job? For store logins, use one dedicated residential IP per store, in the store’s country. Keep it fixed for the life of the store. For a spot check of a page as a buyer, a rotating residential proxy in that country is enough. The IPFoxy website lists a sticky rotation cycle for these proxies.
A sticky session keeps one exit IP for a short time, so a page and its next steps load from the same address. For the data in the table above, you need no proxy at all. This gives a clear rule for each new task. Ask one question first: does this task need my store’s identity? If yes, use the store IP.
If no, and the data is public, use the data API. Use a rotating proxy only to confirm what a local buyer sees. This rule keeps proxy traffic for the tasks that need it, and it keeps each store environment clean.
What you cannot get
EveryInfra returns only publicly visible data, and this limit rules out many tasks. It cannot get content that needs a login, such as private messages, friends-only posts, or seller back-office orders and ad reports. Use the platform’s official API with your own authorization for that. It cannot get platforms or fields that are not in the catalog. Check the catalog first, or open a ticket in the console to ask for them.
Search capabilities return the platform’s ranked results, not every post. In this test, TikTok returned 12 posts. One eBay call returned 200 rows that covered only the last four days. For more coverage, use pages, time slices or more keywords.
Availability is not 100% either. All four indeed/search calls failed in this test. The availability endpoint showed a normal status at the same time. The catalog also lists 27 paused capabilities. Failed calls cost nothing, but they can delay your job.
Production jobs need retries and alerts. Another type of problem is “data came back, but not the data you wanted”. We searched Xiaohongshu with a random string and a limit of the last 24 hours. The platform still returned 20 unrelated notes from September 2025 to October 2026, and the call was charged $0.005556. Always filter the rows by posted_at after you get them.
| Limit | What we saw in this test | What to do |
| Login-only data | Not available by design | Use the official API with your own authorization |
| Ranked results, not every post | TikTok 12 posts, Reddit 25 posts | Use pages, time slices or more keywords |
| Row cap per call | eBay 200 rows covered 4 days | Split by price band or keyword |
| Temporary failures | 4 of 4 Indeed calls returned 503 | Retry with backoff, and alert on repeated failures |
| Unrelated rows | Random string on Xiaohongshu returned 20 notes | Filter by posted_at and by keyword after the call |
Last, there are limits on use. Public does not mean free to copy, republish or sell. Remove or aggregate personal data, such as names, avatars and locations, before analysis and display. This article uses only aggregated results.
You must decide if your use is allowed under the law and the platform terms. We do not give legal advice. Read Google’s user contributed content policy, the platform terms and the robots.txt rules before you start a project.
Industry news: changes in the last 60 days
August 27, 2026: YouTube aligned how it counts public views. The Data API revision history says that long-form videos, Live and Shorts now count a view when a video begins to play. The viewCount field description changed too, and the YouTube Help Center updated the metric definitions. What it means for you: view counts of videos from before and after August 27 are not directly comparable. Split trend analysis by publish date.
September 30, 2026: Reddit published the dates to close its public data API. In a post on r/redditdev, Reddit said that it stops new public API requests on October 31, 2026. From January 12, 2027, it starts to close access for apps that did not register, and it closes all public access in March 2027. RSS feeds stop on November 13. What it means for you: workflows that use Reddit’s free API or RSS for social listening need a new source within months. Our analysis of the Reddit RSS shutdown has more detail.
October 5, 2026: the EU published guidance on the small-parcel duty and handling fee. The guidance from the Commission’s tax and customs department confirms the EUR 3 per item temporary duty from July 1. It adds a EUR 2 per item handling fee, expected from November 1, at the amount in Delegated Regulation (EU) 2026/2152. What it means for you: low-price goods shipped directly to EU buyers carry about $5.60 more fixed cost per item. Compare prices before and after November separately.
October 20, 2026: EssilorLuxottica reported 20% growth in wearables. The press release shows third-quarter revenue of EUR 7,486 million, up 7.2% at constant exchange rates. It also says that new AI glasses will launch for the holiday season. What it means for you: AI glasses are still growing fast, and social discussion will peak around launches. Track them with fixed keywords and fixed time windows, not with a check every few months.
| Date | Change | Source | What to do |
| August 27, 2026 | YouTube counts a public view when playback starts | YouTube Data API revision history | Split view-count trends at this date |
| September 30, 2026 | Reddit sets dates to close its public API and RSS | r/redditdev announcement | Plan a new source before January 12, 2027 |
| October 5, 2026 | EU guidance: EUR 2 handling fee per item from November 1 | DG TAXUD guidance | Compare EU prices before and after November 1 |
| October 20, 2026 | EssilorLuxottica wearables revenue up 20% | Q3 2026 press release | Track AI glasses with fixed keywords and windows |
FAQ
Is scraping public data legal?
This is a common Google suggestion for the query “is scraping public data”. We do not give legal advice. As a data method, EveryInfra returns only publicly visible data. It does not log in and does not get past paywalls.
But public data is not free to use for any purpose. The handling of personal data, republishing and commercial use depend on the law where you are and on the platform terms. Ask your legal team about your specific use before you start.
What is the difference between web scraping and an API?
“Web scraping vs api” is a frequent Google suggestion. An official API gives the structured data that a platform chooses to share. It is usually limited to your own account or app and has quotas. Web scraping gets the content that a page shows in public, and you must parse and maintain it.
EveryInfra sits between the two. It gets public data and returns JSON with fixed fields. See the comparison table above.
Do failed calls cost money?
No. In this test, 4 calls that returned 503 and 1 empty result show charged_usd 0. The ledger lookup shows a full refund. Calls that get 401, 422 or 429 stop before any work starts and never reach billing. Capabilities that bill per block charge only for the blocks that came back.
How long does one call take?
The 40 successful synchronous calls in this test had a median of 20.9 seconds. The range was 2.4 to 92.0 seconds. The server gives a synchronous call about 85 seconds of work time, and the client time is a little longer, so set the timeout to 300 seconds. For slower tasks, add “mode”: “async” to the body and poll the job. Polling is free.
Do I need my own proxy?
Not for EveryInfra. Requests go directly to api.everyinfra.com. Your own programs may need a proxy. Examples are a store login, or a check of a page as a buyer in a given country. For that, use an exit in that country from a proxy provider. To combine the two in one script, see use with a proxy in the docs.
How do I start?
Sign up at everyinfra.com, create an API key in the console and follow the quick start. Read the capability catalog first to check the platform, parameters and price. Try one target with a small limit, and then scale up.
References
- EveryInfra capability catalog (no key needed), EveryInfra, read October 26, 2026: https://api.everyinfra.com/api/v1/social/catalog
- EveryInfra Douyin catalog entry (with rows_per_unit), EveryInfra, read October 26, 2026: https://api.everyinfra.com/api/v1/social/catalog?platform=douyin
- EveryInfra capability availability (Indeed), EveryInfra, read October 26, 2026: https://api.everyinfra.com/api/v1/social/availability?platform=indeed
- EveryInfra OpenAPI 3.0 specification, EveryInfra: https://api.everyinfra.com/openapi.json
- Model Context Protocol Specification 2025-11-25, MCP project: https://modelcontextprotocol.io/specification/2025-11-25
- MCP Specification 2026-07-28 Key Changes, MCP project, July 28, 2026: https://modelcontextprotocol.io/specification/2026-07-28/changelog
- Q3 2026 Revenue, EssilorLuxottica, October 20, 2026: https://www.essilorluxottica.com/en/newsroom/press-releases/q3-2026-revenue/
- The temporary EUR 3 customs duty and the Union handling fee, guidance for Member States and trade, European Commission DG TAXUD, version of October 5, 2026: https://taxation-customs.ec.europa.eu/document/download/053e5b4e-f0be-4f20-9a23-3e3b659a6676_en?filename=Customs%20Guidance%20on%20EUR%203%20customs%20duty.pdf
- Commission Delegated Regulation (EU) 2026/2152, Official Journal of the EU, September 21, 2026: https://eur-lex.europa.eu/eli/reg_del/2026/2152/oj/eng
- Euro foreign exchange reference rates, European Central Bank, October 23, 2026: https://www.ecb.europa.eu/stats/policy_and_exchange_rates/euro_reference_exchange_rates/html/index.en.html
- RMB central parity rates, State Administration of Foreign Exchange (China), October 23, 2026: https://www.safe.gov.cn/AppStructured/hlw/RMBQuery.do
- YouTube Data API Revision History, Google, entry of August 27, 2026: https://developers.google.com/youtube/data/revision_history
- YouTube Data API Quota Calculator, Google: https://developers.google.com/youtube/data/determine_quota_cost
- Place Details (Legacy), Google Maps Platform: https://developers.google.com/maps/documentation/places/web-service/legacy/details
- Google Maps Platform pricing, Google: https://developers.google.com/maps/billing-and-pricing/pricing
- Google Play Developer API reviews.list, Google: https://developers.google.com/resources/api-libraries/documentation/androidpublisher/v3/python/latest/androidpublisher_v3.reviews.html
- List all customer reviews for an app, Apple App Store Connect API: https://developer.apple.com/documentation/appstoreconnectapi/get-v1-apps-_id_-customerreviews
- Buy APIs Requirements, eBay Developers Program: https://developer.ebay.com/api-docs/buy/static/buy-requirements.html
- getItemOffers, Amazon Selling Partner API: https://developer-docs.amazon.com/sp-api/reference/getitemoffers
- TikTok Research Tools: Access and Eligibility, TikTok for Developers: https://developers.tiktok.com/products/research-api/
- X API pay-per-usage pricing, X Developer Platform: https://docs.x.com/x-api/getting-started/pricing
- Yelp Places API: Reviews, Yelp: https://docs.developer.yelp.com/reference/v3_business_reviews
- Job Posting API Overview, LinkedIn (Microsoft Learn): https://learn.microsoft.com/en-us/linkedin/talent/job-postings/api/overview
- Consider all candidates fairly before you apply for an Employment Pass, Ministry of Manpower Singapore, January 5, 2026: https://www.mom.gov.sg/passes-and-permits/employment-pass/consider-all-candidates-fairly
- Pay Transparency, New York State Department of Labor: https://dol.ny.gov/pay-transparency
- Equal Pay and Opportunities Act Q&A, Washington State Department of Labor & Industries: https://lni.wa.gov/workers-rights/wages/equal-pay-opportunities-act/equal-pay-and-opportunities-act-qa
- Equal Pay for Equal Work Act, Colorado Department of Labor and Employment: https://cdle.colorado.gov/dlss/labor-laws-by-topic/equal-pay-for-equal-work-act
- A warning letter (or ten) for businesses: comply with the FTC’s Consumer Review Rule, Federal Trade Commission, December 2025: https://www.ftc.gov/business-guidance/blog/2025/12/warning-letter-or-ten-businesses-comply-ftcs-consumer-review-rule
- The Lau Pa Sat Festival Market at Shenton Way, National Heritage Board Singapore (Roots): https://www.roots.gov.sg/collection-landing/listing/1186692
- Spam policies for Google web search, Google Search Central: https://developers.google.com/search/docs/essentials/spam-policies
- Creating helpful, reliable, people-first content, Google Search Central: https://developers.google.com/search/docs/fundamentals/creating-helpful-content
- RFC 9309: Robots Exclusion Protocol, IETF, 2022: https://www.rfc-editor.org/rfc/rfc9309.html
- Scrapy documentation, Scrapy: https://docs.scrapy.org/en/latest/
- Playwright: Installation, Microsoft: https://playwright.dev/docs/intro
- scrapy/scrapy, GitHub: https://github.com/scrapy/scrapy
- Requests: HTTP for Humans, Requests documentation: https://requests.readthedocs.io/en/latest/
- Maps user contributed content policy, Google: https://support.google.com/contributionpolicy/answer/7400114
- Moving Data API Apps to the Developer Platform: migration dates and next steps, Reddit r/redditdev, September 30, 2026: https://www.reddit.com/r/redditdev/comments/1wubcvf/moving_data_api_apps_to_the_developer_platform/
- Trustpilot Trust Centre, Trustpilot: https://corporate.trustpilot.com/trust
- Tripadvisor’s 2025 Transparency Report, Tripadvisor, March 18, 2025: https://tripadvisor.mediaroom.com/2025-03-18-Tripadvisors-2025-Transparency-Report-reveals-strong-review-submissions-and-improved-fraud-detection
- IPFoxy website (product types, coverage and starting prices, read October 26, 2026), IPFoxy: https://www.ipfoxy.com/
- Videos resource (viewCount field), YouTube Data API: https://developers.google.com/youtube/v3/docs/videos
- Understand your YouTube content performance, YouTube Help: https://support.google.com/youtube/answer/12220281
- Qi Wireless Charging, Wireless Power Consortium: https://www.wirelesspowerconsortium.com/standards/qi-wireless-charging/
Data read on October 26, 2026, from 10:49 to 11:15 Singapore time. Platforms, capabilities and prices change. The current facts are on everyinfra.com and in the capability catalog. The raw responses and the script that computes every number are in the raw/ folder of this draft.